Why we invested in Knonik

Knonik: Building the Data Layer That Robots Learn From
For most of the history of robotics, machines did what they were told. Engineers specified the rules, robots executed them, and performance depended on operating inside environments that matched those assumptions. The shift toward learned behaviour has changed this. Robots can now acquire tasks from demonstration, and the binding constraint has moved from writing control logic to moving data. Today the pace of progress in most robotics teams is set less by model architecture than by how much of the team's engineering time is consumed keeping data pipelines alive.
That consumption is not incidental. Robot demonstration data cannot be scraped off the internet. It has to be acquired . Every data point is physically produced with a robot, sensors and an operator, which makes each one expensive and makes wasted effort downstream costly in a way it is not in language or vision. Yet the tooling around that data is assembled project by project. A new robot, a new task or a new team member triggers another pipeline built from scratch, and the work does not carry forward. Raw teleoperation logs are stored with heavy frame redundancy, so storage costs compound before a single model has trained. A meaningful share of expensive training compute, on the order of 10-30%, is spent with GPUs idle while the dataloader catches up. Annotation is done by hand, which puts engineers on work a machine should be doing. And because there is no signal on episode quality, teams collect hundreds of demonstrations without knowing which are worth training on, discovering the answer only when the model fails. The cost shows up in three places: storage, compute and engineering time.
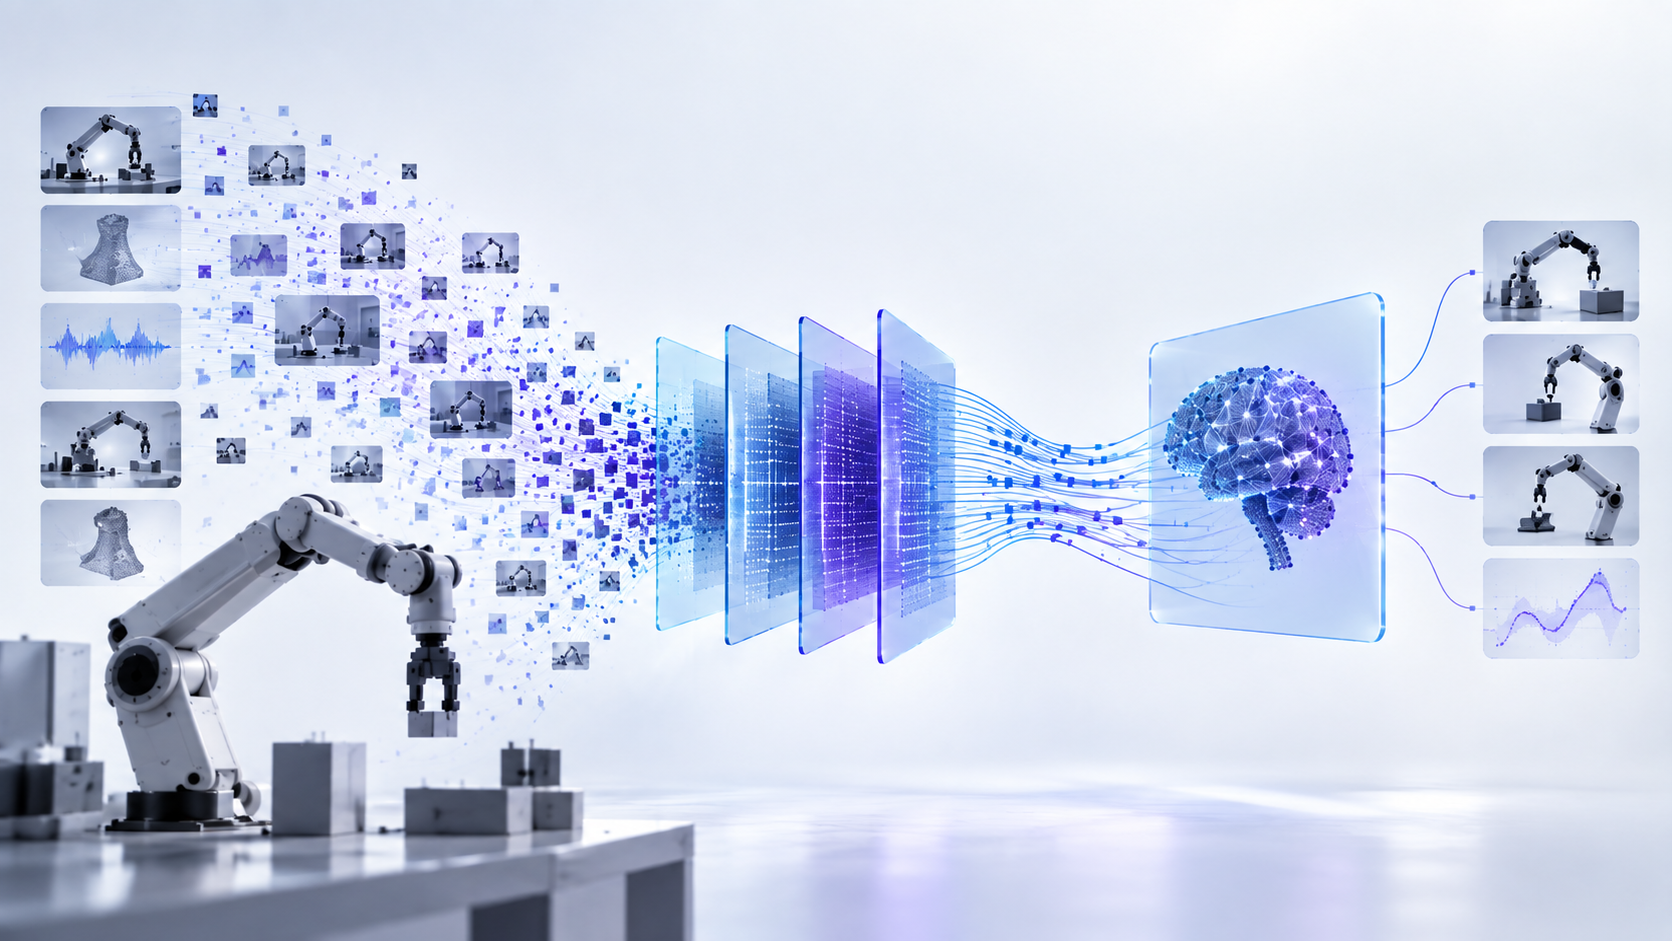
Knonik is building an integrated data infrastructure layer for physical AI to remove that cost. It brings ingestion, normalisation, compression, quality assessment, annotation, visualisation and high performance data loading into a single pipeline deployed inside the customer's own infrastructure, which matters given the sensitivity and gravity of teleoperation data. The design point is that the pipeline is built once and then compounds across robots, tasks and teams, rather than being reconstructed for each. The result is a system shaped around the specific characteristics of robotics data rather than generic ML infrastructure adapted to them.
Strategic Industry and Market Context
The global physical AI market was valued at USD 5.84 billion in 2025 and is projected to reach USD 96 billion by 2035, growing at a CAGR of 32.5%. The robot foundation model layer within it is estimated at USD 1.6 billion in 2025 and projected to reach USD 22.8 billion by 2034. Knonik is serving the storage, compute utilization and tooling market in this layer.
The infrastructure required to manage this data remains fragmented. MLOps platforms were built primarily around cloud based tabular, text and image workloads, while existing data labelling platforms were designed around perception rather than action and policy level data. Robotics teams are therefore forced to combine multiple tools with custom engineering at every interface, while the largest robotics companies increasingly build their own infrastructure internally.
This creates a significant gap for early stage robotics companies, university spinouts and research laboratories that need production grade infrastructure but do not have the engineering resources to build and maintain it themselves. As physical AI scales, the ability to turn recorded experience into training ready data efficiently will become an increasingly important part of the robotics stack.
Key Advantages of Knonik's Platform
The company is building an on-premise data infrastructure that sits between raw robot sensor recordings and GPU training clusters. The core problem Knonik addresses is the inefficiency of the default robotics data pipeline. The industry standard of storing raw
frames in uncompressed HDF5 files and serving them via a generic dataloader was not designed for robotics. It produces oversized files, leaves GPUs idle for 37–40% of training time, and introduces significant instability across random seeds. Knonik's compression technology reduces the time period that GPUs are idle, saving on electric power usage and GPU management costs. There are four aspects of the platform: i) The platform covers the full workflow from ingestion to training, so improvements at each stage to compound rather than being lost at the interfaces between separate tools. ii) Knonik runs inside the customer's own infrastructure, which suits teams holding sensitive training data within their existing environments and shortens the security reviews. iii) The platform has demonstrated meaningful improvements in data loading and storage efficiency across robotics datasets, while maintaining the quality of the underlying training data. iv) The data layer becomes more valuable as it sees more of the training workflow. By observing ingestion, quality, annotation and loading together, Knonik can progressively move from managing datasets toward understanding which data should be used for which training runs.
The combination of an integrated architecture, deployment within customer infrastructure and performance advantages gives Knonik a differentiated position in a category that remains fragmented. Over time, the company also has the opportunity to become a standardised data ingestion layer for robotics.
Knonik is led by Arjun P S, an embodied AI researcher with an electrical, electronics and communication engineering background from IIT/ISM Dhanbad. His research experience includes collaborations with researchers at the University of Bremen and IIIT Allahabad, four published papers, and winning teams at the NeurIPS 2023 HomeRobot Open Vocabulary Mobile Manipulation Challenge and the CVPR 2024 Embodied AI Challenge.